 GrowKitt
Research › Pilot study
🔬 Pilot · n = 25 · checked live 23 October 2026The AI-Readiness of Indian D2C Websites
Every number on this page comes from real HTTP checks we ran against live websites on 23 October 2026. Nothing is estimated or taken from a database — and the raw per-site data is downloadable, so you can verify any cell in the table below yourself. Prefer the short version? Read the 7-minute blog write-up of this study.
100%
have an llms.txt file
…but keep reading — it's not what it looks like
4%
block GPTBot (OpenAI)
Indian D2C is wide open to AI crawlers
12%
have FAQ schema
the markup that gets you QUOTED in AI answers
36%
have titles ≤ 60 characters
64% overflow what Google displays
Citable stats — copy, paste, link back
Writing about AI readiness in India? These six numbers are free to cite with attribution (CC-BY) — each has a permanent anchor link and the raw data to back it.
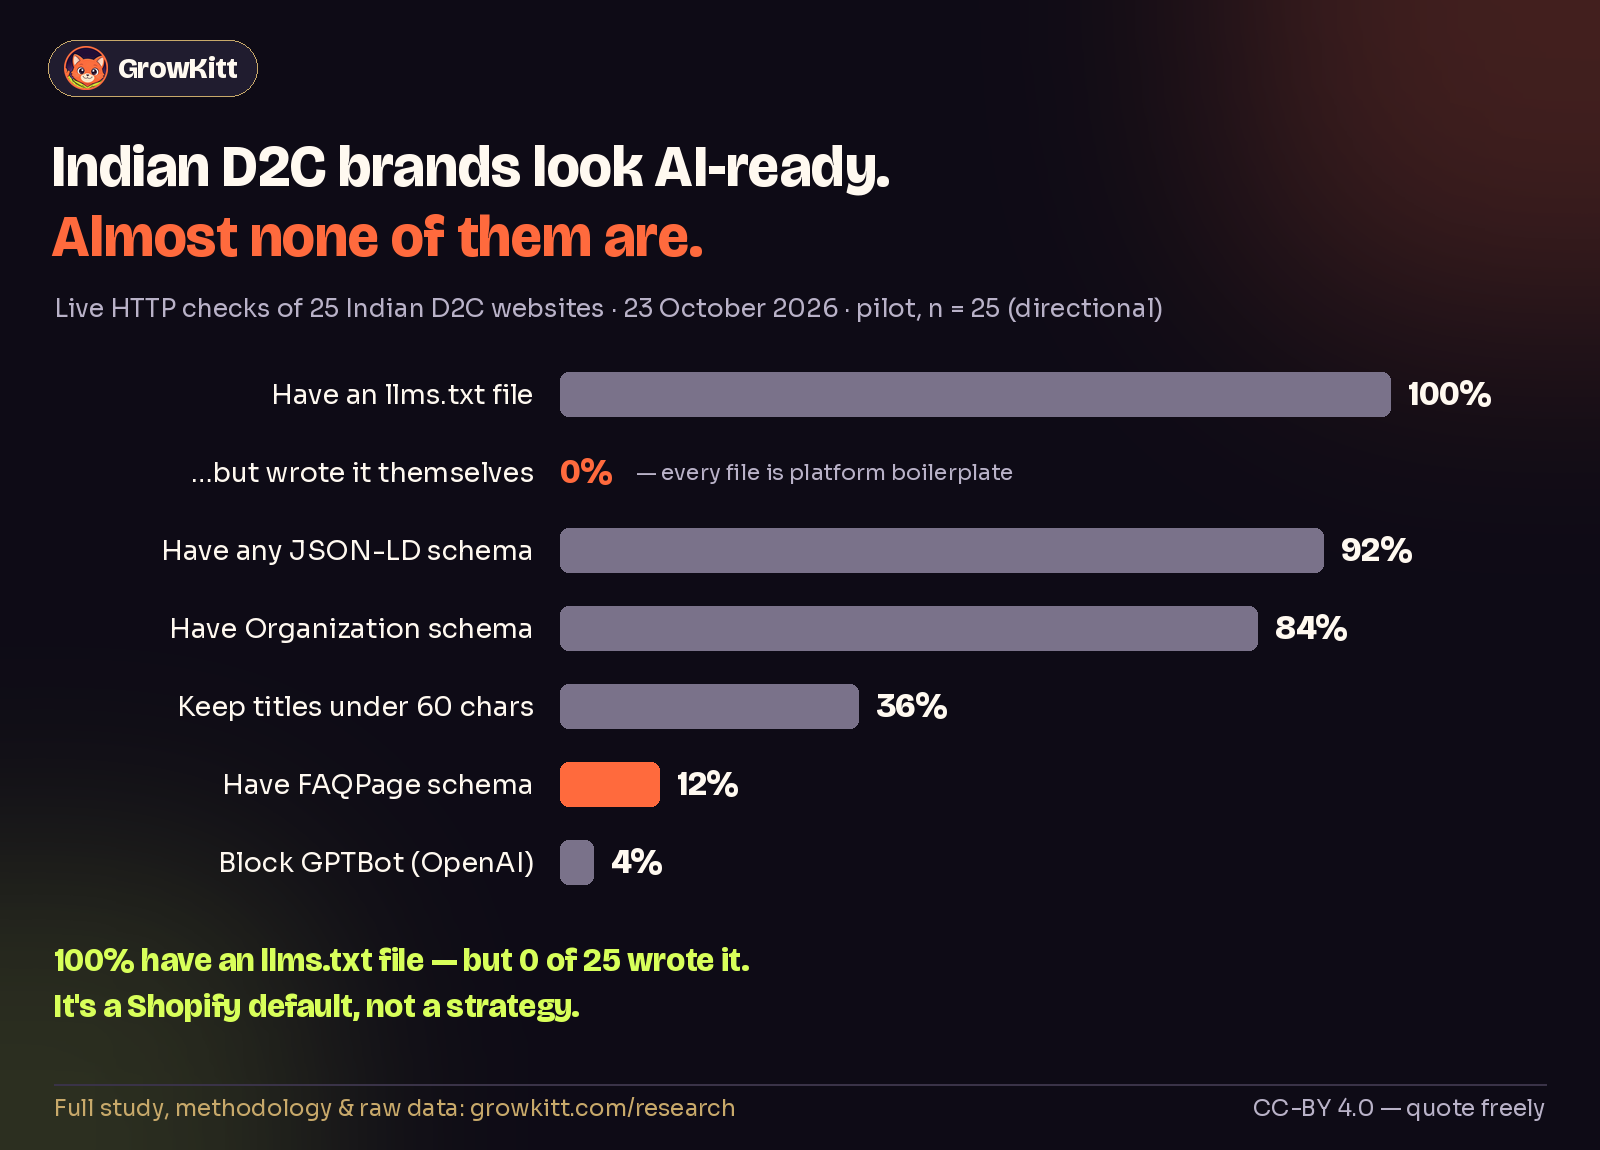
100% (25/25) of checked Indian D2C websites have an llms.txt file — all of it platform boilerplate, none hand-written. (GrowKitt pilot study, Oct 2026 — growkitt.com/research)
Only 4% (1/25) of checked Indian D2C websites block GPTBot, and 0% block PerplexityBot — Indian D2C is wide open to AI crawlers. (GrowKitt pilot study, Oct 2026 — growkitt.com/research)
Just 12% (3/25) of checked Indian D2C websites carry FAQPage schema — the markup most associated with being quoted in AI answers. (GrowKitt pilot study, Oct 2026 — growkitt.com/research)
64% (16/25) of checked Indian D2C homepages have title tags longer than 60 characters — overflowing what Google displays. (GrowKitt pilot study, Oct 2026 — growkitt.com/research)
92% (23/25) of checked Indian D2C websites carry some JSON-LD structured data, and 84% have Organization/Store markup — but only 12% have the FAQ markup that earns AI citations. (GrowKitt pilot study, Oct 2026 — growkitt.com/research)
0 of 25 checked Indian D2C websites had a hand-written llms.txt — 'AI readiness on paper' arrived via platform defaults, not merchant action. (GrowKitt pilot study, Oct 2026 — growkitt.com/research)
Finding 1 — The 100% llms.txt number is not what it looks like
All 25 sites have an llms.txt file — which would be a stunning adoption story, except for what we found when we opened the files: nearly all of them are auto-generated by Shopify, identical "Agent Instructions / Shop skill" boilerplate with only the brand name swapped in. (We verified this by fetching each file and comparing contents, and ruled out soft-404 false positives by testing garbage paths on the same domains.)
The real story: Indian D2C brands became "AI-ready" on paper without a single merchant lifting a finger. Platform defaults — not marketing teams — are currently deciding how AI agents see Indian online commerce. A generic shop-skill file tells AI engines how to browse your catalogue; it does not tell them why anyone should buy from you. That layer — the one that affects recommendations — is still almost universally missing.
Finding 2 — The door is wide open: almost nobody blocks AI crawlers
Only 1 of 25 sites blocks GPTBot in robots.txt (1 blocks Google-Extended, 0 block PerplexityBot). Contrast that with Western publishing, where GPTBot blocking became common — Indian D2C has effectively decided, mostly by default, to be fully visible to AI engines. That means the AI-visibility winners here will be decided by content quality and structured data, not by access. Which brings us to the gap:
Finding 3 — The actual gap: FAQ schema at 12%, titles failing at 64%
92% of sites carry some JSON-LD schema and 84% have Organization/Store markup — again largely platform defaults. But FAQPage schema — the single strongest "quote me" signal for AI answers — appears on just 3 of 25 sites. And only 36% of homepages keep their title within the 60 characters Google actually displays. The baseline is handled by platforms; the layer that wins AI citations is almost untouched.
Methodology — exactly what we did
- Sample: 25 well-known Indian D2C brand websites, hand-assembled and then live-verified (HTTP 200 with real content) on 23 October 2026. Sites that were unreachable or bot-blocked were dropped, not guessed.
- Checks per site: llms.txt presence and content inspection (with soft-404 garbage-path controls); robots.txt rules for GPTBot, Google-Extended, PerplexityBot and CCBot; JSON-LD schema types on the homepage; homepage title length; meta description presence; sitemap declaration.
- Tools: the same checks GrowKitt's Bulk Site Audit and Website Fix-It run, executed live.
- Raw data: ai-readiness-pilot-2026-raw.json — every per-site result, machine-readable, CC-BY 4.0. Quote freely with a link to this page.
Honest limitations
- n = 25 is a pilot, not a verdict. Treat the percentages as directional.
- The sample is online-first D2C brands, most on Shopify — it is not representative of Indian SMBs broadly. Traditional service businesses (clinics, CAs, manufacturers) likely look very different; that contrast is exactly what the full two-cohort study will measure.
- Checks cover the homepage and root files only — no full-site crawl in the pilot.
Per-site results — verify any row yourself
All 25 sites have llms.txt (see Finding 1). Checked live, 23 October 2026 — results may change as sites update, which is rather the point.
| Site | GPTBot | Schema | FAQ schema | Title length |
|---|---|---|---|---|
| arata.in | ✅ allowed | ✅ | ✅ | ✅ 36 ch |
| beminimalist.co | ✅ allowed | ✅ | — | ⚠️ 63 ch |
| blissclub.com | ✅ allowed | ✅ | — | ✅ 51 ch |
| bluetokaicoffee.com | ✅ allowed | ❌ | — | ⚠️ 61 ch |
| bombayshavingcompany.com | ✅ allowed | ✅ | — | ⚠️ 69 ch |
| bunaai.com | ✅ allowed | ✅ | — | ⚠️ 74 ch |
| chaayos.com | ✅ allowed | ❌ | — | ✅ 14 ch |
| chumbak.com | ✅ allowed | ✅ | — | ✅ 33 ch |
| countrybean.in | ✅ allowed | ✅ | — | ✅ 37 ch |
| discoverpilgrim.com | ✅ allowed | ✅ | — | ⚠️ 67 ch |
| juicychemistry.com | ✅ allowed | ✅ | — | ⚠️ 62 ch |
| khadinatural.com | ✅ allowed | ✅ | — | ⚠️ 70 ch |
| mcaffeine.com | ✅ allowed | ✅ | — | ⚠️ 87 ch |
| neemans.com | ✅ allowed | ✅ | ✅ | ✅ 46 ch |
| nurserylive.com | ✅ allowed | ✅ | — | ⚠️ 66 ch |
| okhai.org | ✅ allowed | ✅ | — | ⚠️ 70 ch |
| phool.co | ✅ allowed | ✅ | — | ✅ 54 ch |
| plumgoodness.com | ✅ allowed | ✅ | — | ⚠️ 62 ch |
| sleepycat.in | ✅ allowed | ✅ | — | ⚠️ 72 ch |
| sleepyowl.co | ✅ allowed | ✅ | ✅ | ⚠️ 94 ch |
| soulflower.in | ✅ allowed | ✅ | — | ⚠️ 73 ch |
| suta.in | ✅ allowed | ✅ | — | ⚠️ 67 ch |
| teabox.com | ✅ allowed | ✅ | — | ✅ 58 ch |
| ugaoo.com | 🚫 blocked | ✅ | — | ✅ 43 ch |
| zouk.co.in | ✅ allowed | ✅ | — | ⚠️ 75 ch |
Where does YOUR site stand on these exact checks?
The free scan runs the AI-readiness basics on your site in your browser. The desktop app's Bulk Site Audit and llms.txt Generator go page-by-page — and write the fixes.
Journalists & bloggers: quote any number with a link to this page. Questions about methodology → sales@growkitt.com — details on the press page.